September 29, 2026
LP Spotlight: Kartik Hosanagar
Q&A with Kartik Hosanagar, Rohati LP
Investing Partner
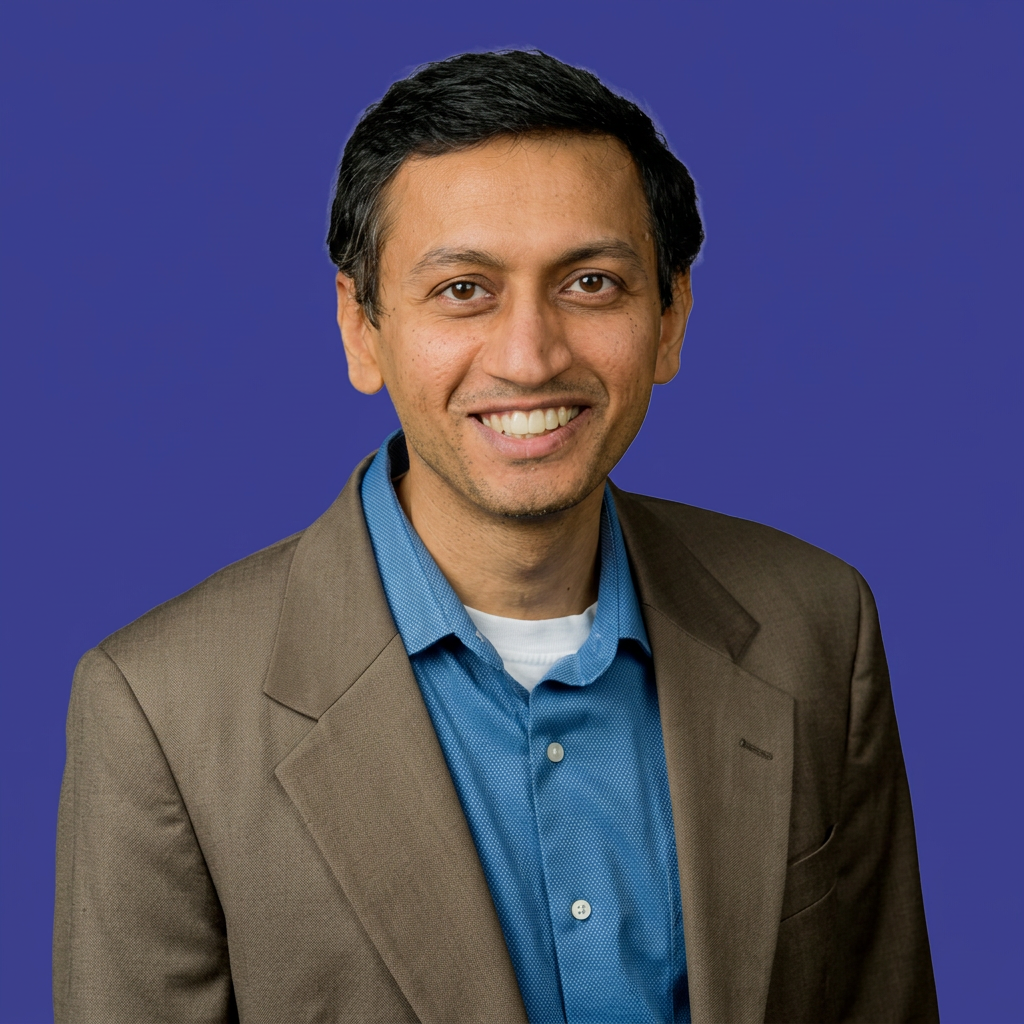
Kartik Hosanagar teaches AI for Business at the Wharton School, co-directs Wharton Human-AI Research, and is founder and CEO of Bodhium Labs, an applied AI lab focused on marketing. He is also a Rohati Capital limited partner. Rohati General Partner Nick Talwar met Kartik while taking his weeklong AI course, and Kartik later joined the team offsite in August. For this conversation, Rohati Investing Partner Charles Elkan, who ran Amazon's Core ML team and led machine learning globally at Goldman Sachs, asks Kartik how to tell a real AI moat from a story about one.
Competitive advantage in AI is shifting from model access to data flywheels. What does a real data flywheel look like at the early stage, and how can an investor tell a genuine one from a story?
Hosanagar: Data is one way to build an AI moat, but a data flywheel is not merely a lot of proprietary data. Bloomberg had proprietary financial data and spent enormous resources training BloombergGPT, but within a year GPT from OpenAI matched or beat it on the very tasks it was built for. Having more data than the next company, or fine-tuning your own model, doesn't give you a moat, because foundation models improve so fast that any static advantage commoditizes.
A real flywheel has to satisfy two conditions. Learning from one user has to improve the product for other users, a data network effect. And that improvement has to ship fast enough to matter during the current product's usage lifetime, not the next generation's. In other words, it needs to provide cross-user benefit and speed.
At the early stage, that looks like a product designed so ordinary usage generates labeled training signal as a byproduct. When a user edits an AI-drafted email, that edit is a labeled example of "wrong email and right email." When a developer accepts or rejects a code suggestion, that's a quality signal. Grammarly and GitHub Copilot are the textbook cases, where every accept or reject flows back into the product and the loop compounds: better suggestions lead to more usage, more usage produces more signal, and more signal produces better suggestions. What makes that defensible is the loop mechanics rather than the model itself, meaning the feedback extraction, the evaluation harness, the training pipeline, and the release cadence.
So how does an investor tell the "real thing" from a pitch deck? I'd ask three questions. How does this product get smarter every single time someone uses it? How fast does that learning reach the next user: minutes, a release cycle, or the next model? And which layers does the company own, and which does it rent? If the intelligence is rented from a shared API and everything else is a thin wrapper, differentiation is shallow.
Your research found that when teams use AI without a structured process, average quality goes up but the diversity of ideas drops sharply. What should that change about how a startup integrates AI?
Hosanagar: The headline finding is a paradox. Across four studies spanning short-story writing, innovation, and humor caption contests, we found that AI reliably raised the average quality of individual output. It raised the floor, and it helped the least experienced people the most. But collectively it compressed the idea space: when everyone used AI, their outputs became more similar to one another, and the diversity that produces genuine breakthroughs dropped. That's a real problem for a startup, whose whole reason to exist is a non-obvious idea, so use AI to make execution and workflows more efficient, but don't outsource the creative thinking and vision.
The most actionable result is that the stage at which AI enters the workflow matters as much as whether you use it at all. When AI was used in idea generation, diversity collapsed. When it was used for execution, after humans had generated the raw ideas, quality and productivity held at similar levels, and variety stayed higher than under full reliance on AI.
So, keep humans in the driver's seat for brainstorming and problem framing, and use AI downstream for drafting, refinement, scaling, and evaluation.
Your AI for Business course includes a case study on how AI threatens traditional SaaS and what reinventing SaaS around AI will look like. From an early-stage investor's seat, which categories are most exposed to AI displacement, and which hold up best?
Hosanagar: The way I think about SaaS exposure is to ask what the moat actually was, and then ask whether AI dissolves it. The classic software moats are network effects, platform and ecosystem lock-in, deep integration into a customer's workflow and systems, bundling, proprietary data, and distribution. AI doesn't threaten all of these equally.
The most exposed category is software whose value was essentially a structured interface over a database, meaning a workflow, a set of forms, and some reporting on top of a system of record. AI is an existential threat there, because a capable agent can increasingly do the workflow directly rather than presenting a human with a screen to do it in. Think templated content tools, single-purpose "GPT wrapper" point solutions, generic horizontal productivity add-ons, first-line support and BPO-style tooling, and thin analytics and BI layers. Anything where the underlying task is verifiable and repetitive is vulnerable.
What holds up better is software with a moat AI doesn't touch: genuine network effects, deep integration across multiple systems (especially in regulated markets), high switching costs, distribution advantages, and, most relevant to this conversation, a real data flywheel where the product compounds with use. Vertical, industry-specific products tend to be more defensible than horizontal ones, because the integration and the domain data are harder to replicate.
Your course also covers starting an AI venture without proprietary data. What does the playbook look like for a founder who doesn't have a data moat on day one?
Hosanagar: First, almost no one has a data moat on day one. You need a product to generate data, but you need data to build a differentiated product, and that chicken-and-egg problem is the normal starting condition. What matters is having a credible path from zero to a flywheel. I've seen companies get there in a few ways.
Start with a non-AI (or lightly AI) service. Solve a real problem in a way that generates usage data as a byproduct, then layer intelligence on top. Facebook built the social graph before the personalization AI, and Lemonade ran insurance before its claims AI got good.
Partner with a data-rich organization that lacks AI expertise. Hospitals, manufacturers, and insurers sit on proprietary datasets but can't always build. You can trade early or exclusive access for anonymized training data.
Crowdsource labels, ideally inside the workflow. Amazon Mechanical Turk and Scale work for explicit labeling, but a more elegant example is Google's CAPTCHA, where users label data for free as a side effect of using the product.
Use public data as a starting point. There's far more usable public data than founders assume. BlueDot flagged COVID from public health statements, news, and airline ticketing. Public data isn't defensible on its own, so you combine it with proprietary data over time.
Rethink whether you need labeled data at all. Reinforcement learning and verifiable rewards can substitute for labels. AlphaZero used zero human training data and still became the best Go-playing AI, because reinforcement learning let it bootstrap its own improvement without a dataset.
So on day one, your edge rarely comes from the data itself but from the loop you design to acquire that data and compound it.
What are you working on these days?
Hosanagar: My latest project is Bodhium Labs, an applied AI lab focused on marketing, where we're applying reinforcement learning to build self-improving marketing systems. Our first product helps companies increase their visibility in AI search.
For every company, AI is changing the buyer's purchase journey. Your buyer used to scan ten blue links and choose a product after visiting a few websites. Now they ask ChatGPT, Claude, or Google's AI Overviews and act on the one answer it gives back. Marketers aren't fighting for a rank anymore; they're fighting to be that recommendation.
Today's generative engine optimization (GEO) tools score how often you're recommended, but none tell you how to become the recommendation, or whether a strategy will work before you commit a full quarter to a campaign, with all the new content, brand reviews, and legal reviews that come with it. To me, it feels like marketers are test-flying live and in the dark, when what they need is a flight simulator for AI search.
That's why our first product is an LLM simulator. Our agents develop hundreds of GEO strategies and test whether any of them move your AI visibility, so the poor ones crash in the sim rather than in the market. Marketers waste less effort on losing strategies and compound what they learn faster than their competitors. In early runs with over a dozen companies, we found winning strategies in weeks, not quarters.
And this is just our first product. We plan to use similar techniques to solve a range of other problems in marketing.
Enjoyed this piece? We’d love to hear from you.
admin@rohati.capital